# The Future Feels Like 1,000 Tokens a Second

Source: https://www.bobzhu.tech/the-future-feels-like-1000-tokens-a-second/
Markdown: https://www.bobzhu.tech/assets/agents/the-future-feels-like-1000-tokens-a-second.md
Tags: Essays, AI, Systems

Summary: Cerebras is interesting beyond its IPO because near-1,000-token-per-second inference changes the shape of the work: draft, check, repair, compare, and return before the human loses the thread.

Feature image: https://storage.ghost.io/c/ea/80/ea80b01b-c9d0-45fd-a95f-5fbcd52ed925/content/images/2026/05/fast-inference-feature.png
Feature image alt: Hand-drawn editorial illustration of a notebook, stopwatch, and small task loops branching from one human decision point.
Feature image caption: Fast inference changes how many useful loops can stay inside one human attention window.

<p>The strange thing about a very fast model is that it makes the old interface feel theatrical.</p>

<p>The streaming cursor. The slow paragraph forming line by line. The little pause where you convince yourself the model is thinking. The agent timeline that turns a small request into a job you are meant to check later.</p>

<p>Some of that is real work. A lot of it is latency dressed up as product design.</p>

<p>This is why <a href="https://www.cerebras.ai/">Cerebras</a> has been sitting in my head. The obvious story is that the company <a href="https://www.cerebras.ai/press-release/cerebras-systems-announces-filing-of-registration-statement-for-proposed-initial-ipo">filed its S-1 for a proposed IPO</a> on 17 April 2026, with a planned Nasdaq ticker of <code>CBRS</code>. That makes it a market story.</p>

<p>I think the more useful story is stranger than that.</p>

<p>At close to 1,000 output tokens per second, the model response stops feeling like a thing you wait for. It starts feeling like something you can move through.</p>

<p>That changes the unit of work.</p>

<h2 id="the-wait-was-shaping-the-software">The wait was shaping the software</h2>

<p>Most AI products still carry the assumptions of slow inference.</p>

<p>You ask. You wait. You watch the output arrive. You decide whether to retry. If the task has several steps, the product usually turns it into a background agent run: queue it, stream progress, show a timeline, tell the user to come back later.</p>

<p>That design made sense because waiting changes behaviour. If a model takes 20, 40, or 90 seconds to work through a task, the human will usually leave the thought. They open another tab. They start another agent. They half-supervise three things and properly supervise none of them.</p>

<p>Then, later, they return to a result and try to remember what they were asking for in the first place.</p>

<p>Fast inference attacks that problem from a different direction. It does not make the model automatically better. It makes the loop shorter enough that the human can stay inside it.</p>

<p>That is the part I care about.</p>
<div class="reader-artifact reader-artifact-note" data-reader-reference="" data-reader-reference-kind="Note" data-reader-reference-title="The actual claim" data-reader-reference-detail="The speed is useful when it keeps judgement, correction, and comparison close to the human." data-reader-typewriter="">
  <p class="reader-note-body" data-reader-typewriter-target="">
    Fast inference is not interesting because it prints text quickly. It is interesting because it lets more supervised attempts happen before attention breaks.
  </p>
</div>
<h2 id="scaling-thinking-is-smaller-than-it-sounds">Scaling thinking is smaller than it sounds</h2>

<p>I keep coming back to the phrase "scaling human thinking", but I do not mean it in a grand way.</p>

<p>I mean something quite ordinary.</p>

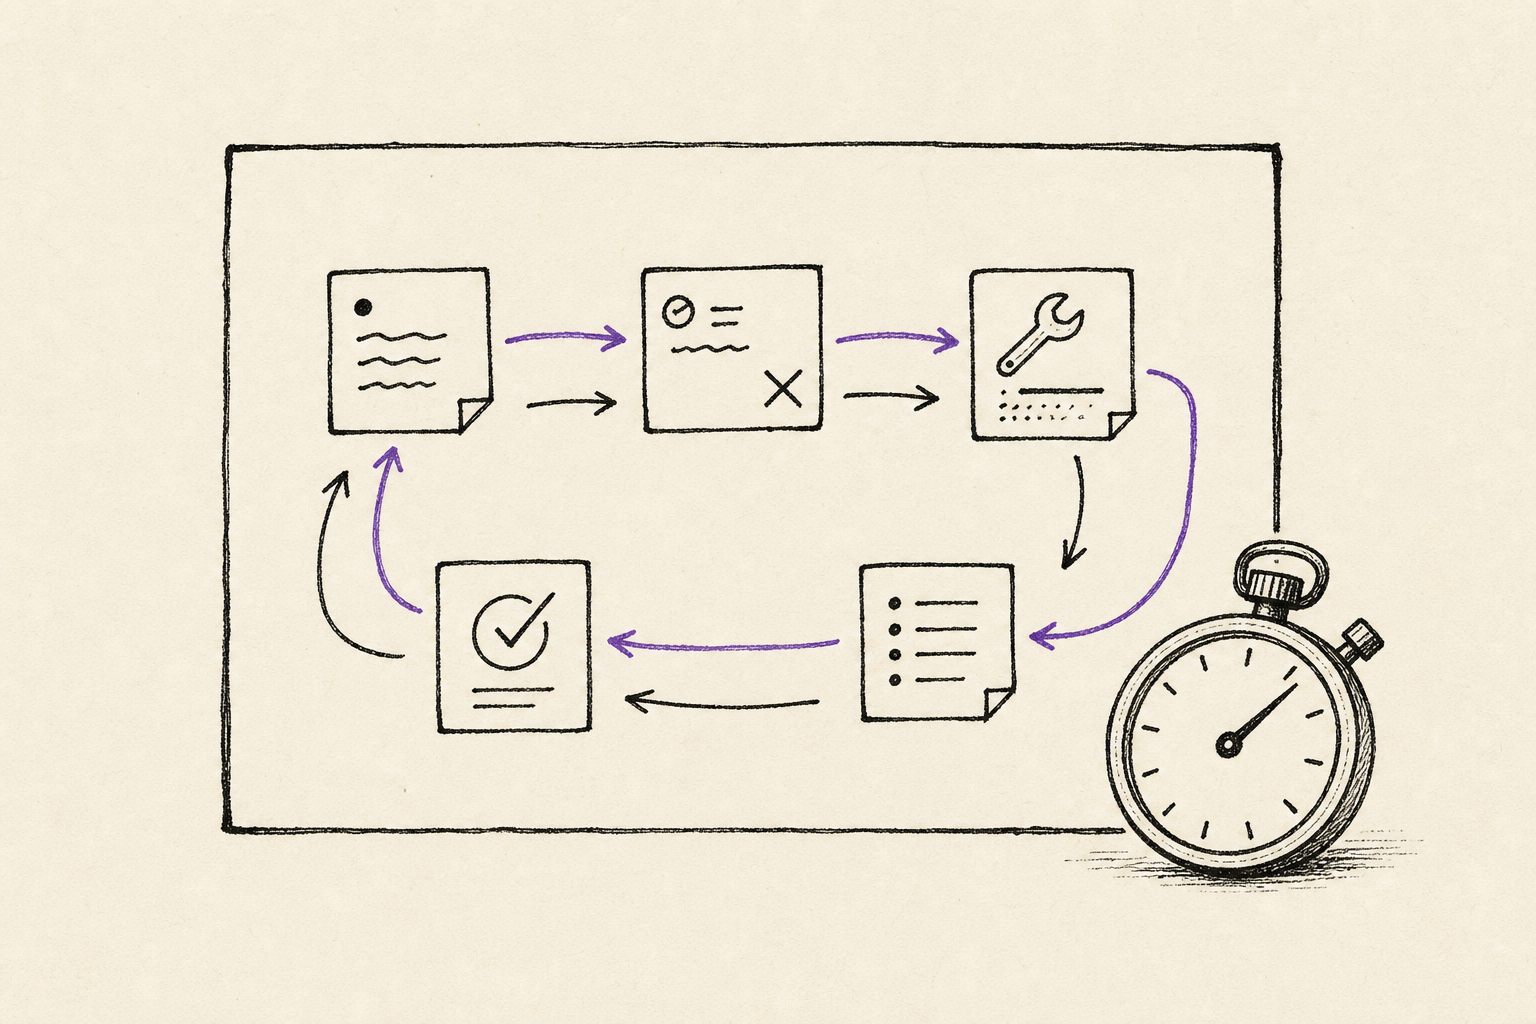
<p>One person can run more drafts, checks, critics, tool calls, variants, and repairs while they still remember what they were trying to do.</p>

<p>That is enough to change the work.</p>

<p>For a coding task, the old loop might be:</p>

<ol><li>Ask for a patch.</li>
<li>Wait.</li>
<li>Read the patch.</li>
<li>Ask for a review.</li>
<li>Wait again.</li>
<li>Ask for a fix.</li>
<li>Lose patience or switch tabs.</li></ol>

<p>The faster loop can feel more like:</p>

<ol><li>Draft it.</li>
<li>Criticise it.</li>
<li>Repair the weak bit.</li>
<li>Check the risky assumption.</li>
<li>Show me what still needs human judgement.</li></ol>

<p>Same human. Same task. More thinking passes before the moment goes cold.</p>

<figure class="kg-card kg-image-card kg-card-hascaption"><img src="https://storage.ghost.io/c/ea/80/ea80b01b-c9d0-45fd-a95f-5fbcd52ed925/content/images/2026/05/fast-inference-attention-window.png" class="kg-image" alt="Hand-drawn diagram of several small AI work loops contained inside one framed attention window beside a stopwatch." loading="lazy"><figcaption>The useful threshold is when several checks and repairs fit inside the same attention window.</figcaption></figure>

<p>This is different from saying the model is thinking like a person. It is not. The person still supplies intent, taste, rejection, direction, and the final judgement.</p>

<p>The model supplies motion.</p>

<p>The faster the motion gets, the more of it can remain supervised.</p>

<h2 id="the-current-fast-lane">The current fast lane</h2>

<p>The public example I would start with is <a href="https://www.cerebras.ai/code">GLM 4.7 on Cerebras Code</a>.</p>

<p>Cerebras positions GLM 4.7 as a coding model running at <code>1,000+</code> output tokens per second. Its <a href="https://inference-docs.cerebras.ai/resources/glm-47-migration">migration docs</a> list the Cerebras model ID as <code>zai-glm-4.7</code>, describe a roughly 358B-parameter mixture-of-experts model with about 32B active parameters, and note support for about a 131k context window with up to 40k completion tokens.</p>

<p>That combination is the point: capable enough to be useful, fast enough to change the shape of the interaction.</p>
<div class="reader-artifact reader-artifact-model-card" data-reader-artifact="model-card">
  <div class="reader-model-header">
    <div>
      <h3 class="reader-artifact-title reader-model-name">Cerebras fast lane</h3>
      <p class="reader-model-summary">The public signal is not a leaderboard crown. It is a coding-capable model served quickly enough to keep loops close.</p>
    </div>
    <div class="reader-model-meta">
      <span class="reader-model-lab">Cerebras</span>
      <span class="reader-model-date">May 2026</span>
    </div>
  </div>
  <div class="reader-model-stats">
    <div class="reader-model-stat">
      <span class="reader-model-stat-label">Model</span>
      <span class="reader-model-stat-value">GLM 4.7</span>
      <span class="reader-model-stat-detail">public coding surface</span>
    </div>
    <div class="reader-model-stat">
      <span class="reader-model-stat-label">Speed</span>
      <span class="reader-model-stat-value">1,000+</span>
      <span class="reader-model-stat-detail">output tokens per second</span>
    </div>
    <div class="reader-model-stat">
      <span class="reader-model-stat-label">Fit</span>
      <span class="reader-model-stat-value">motion</span>
      <span class="reader-model-stat-detail">draft, check, repair</span>
    </div>
  </div>
  <div class="reader-model-tags">
    <span class="reader-model-tag">coding</span>
    <span class="reader-model-tag">fast loop</span>
    <span class="reader-model-tag">executor</span>
  </div>
</div>
<p>The private example is <a href="https://www.cerebras.ai/blog/cerebras-kimi-k2-Enterprise">Kimi K2.6 on Cerebras</a>.</p>

<p>Cerebras says Artificial Analysis measured Kimi K2.6 at 981 output tokens per second on 6 May 2026 through a private Cerebras endpoint. It also says a request with 10,000 input tokens and 500 output tokens completed in 5.6 seconds on Cerebras, compared with 163.7 seconds on the official Kimi endpoint in that test.</p>

<p>That is a serious number. It is also important to describe it accurately. Cerebras frames Kimi K2.6 as an enterprise customer trial / dedicated endpoint, not broad public self-serve access.</p>

<p>I do not want the article to become a Kimi post. Kimi is the measurement anchor. The bigger shift is that a trillion-parameter open-weight agentic model can be served quickly enough to feel interactive.</p>

<p><a href="https://huggingface.co/moonshotai/Kimi-K2.6">The Kimi K2.6 model card</a> makes the scale clear: 1T total parameters, 32B active parameters, long context, multimodal input, tool use, and a Modified MIT licence. Those details matter. But the speed is what turns the details into a different product surface.</p>

<h2 id="the-interface-gets-exposed">The interface gets exposed</h2>

<p>Cerebras' own <a href="https://inference-docs.cerebras.ai/resources/designing-for-cerebras">design guidance</a> is unusually revealing here because it moves the conversation away from benchmark bragging.</p>

<p>At very high token rates, the UI can become the bottleneck. Rendering every streaming chunk can be slower than generation. Short answers may not need streaming. Multi-step agent loops that previously took 30 to 60 seconds can move closer to real time. Voice systems can become bottlenecked by speech-to-text and text-to-speech rather than the LLM call.</p>

<p>That is not a tiny implementation note.</p>

<p>That is the product admitting that the old theatre might be in the wrong place.</p>
<div class="reader-artifact reader-artifact-browser" data-reader-artifact="browser">
  <div class="reader-browser-chrome">
    <div class="reader-browser-tabs">
      <span class="reader-browser-tab is-active">Docs</span>
      <span class="reader-browser-tab">Benchmark</span>
      <span class="reader-browser-tab">Model card</span>
    </div>
    <span class="reader-browser-url">cerebras.ai / inference-docs / huggingface.co</span>
  </div>
  <div class="reader-browser-panel">
    <p class="reader-browser-summary">The source pass changes the claim from "this model is fast" to "the client, queue, and streaming assumptions now need redesigning".</p>
    <div class="reader-browser-sources">
      <div class="reader-browser-source">
        <span class="reader-browser-source-index">1</span>
        <div>
          <p class="reader-browser-source-title">GLM 4.7 migration docs</p>
          <p class="reader-browser-source-detail">Model ID, context, output, and reasoning-mode details.</p>
        </div>
        <span class="reader-browser-source-status">verified</span>
      </div>
      <div class="reader-browser-source">
        <span class="reader-browser-source-index">2</span>
        <div>
          <p class="reader-browser-source-title">Cerebras design guide</p>
          <p class="reader-browser-source-detail">UI buffering, streaming, agent loops, and voice latency implications.</p>
        </div>
        <span class="reader-browser-source-status">current</span>
      </div>
      <div class="reader-browser-source">
        <span class="reader-browser-source-index">3</span>
        <div>
          <p class="reader-browser-source-title">Kimi K2.6 enterprise trial</p>
          <p class="reader-browser-source-detail">981 output tokens per second through a private Cerebras endpoint.</p>
        </div>
        <span class="reader-browser-source-status">caveated</span>
      </div>
    </div>
  </div>
</div>
<p>If the model is slow, streaming is a kindness. If the model is fast, streaming can be a costume. It tells the user "work is happening" even when the work already happened and the browser is just catching up.</p>

<p>This is why fast inference feels like a product primitive. It changes what you bother building around the model.</p>

<h2 id="the-ceiling-still-belongs-in-the-room">The ceiling still belongs in the room</h2>

<p>This is where I would be careful with the comparison.</p>

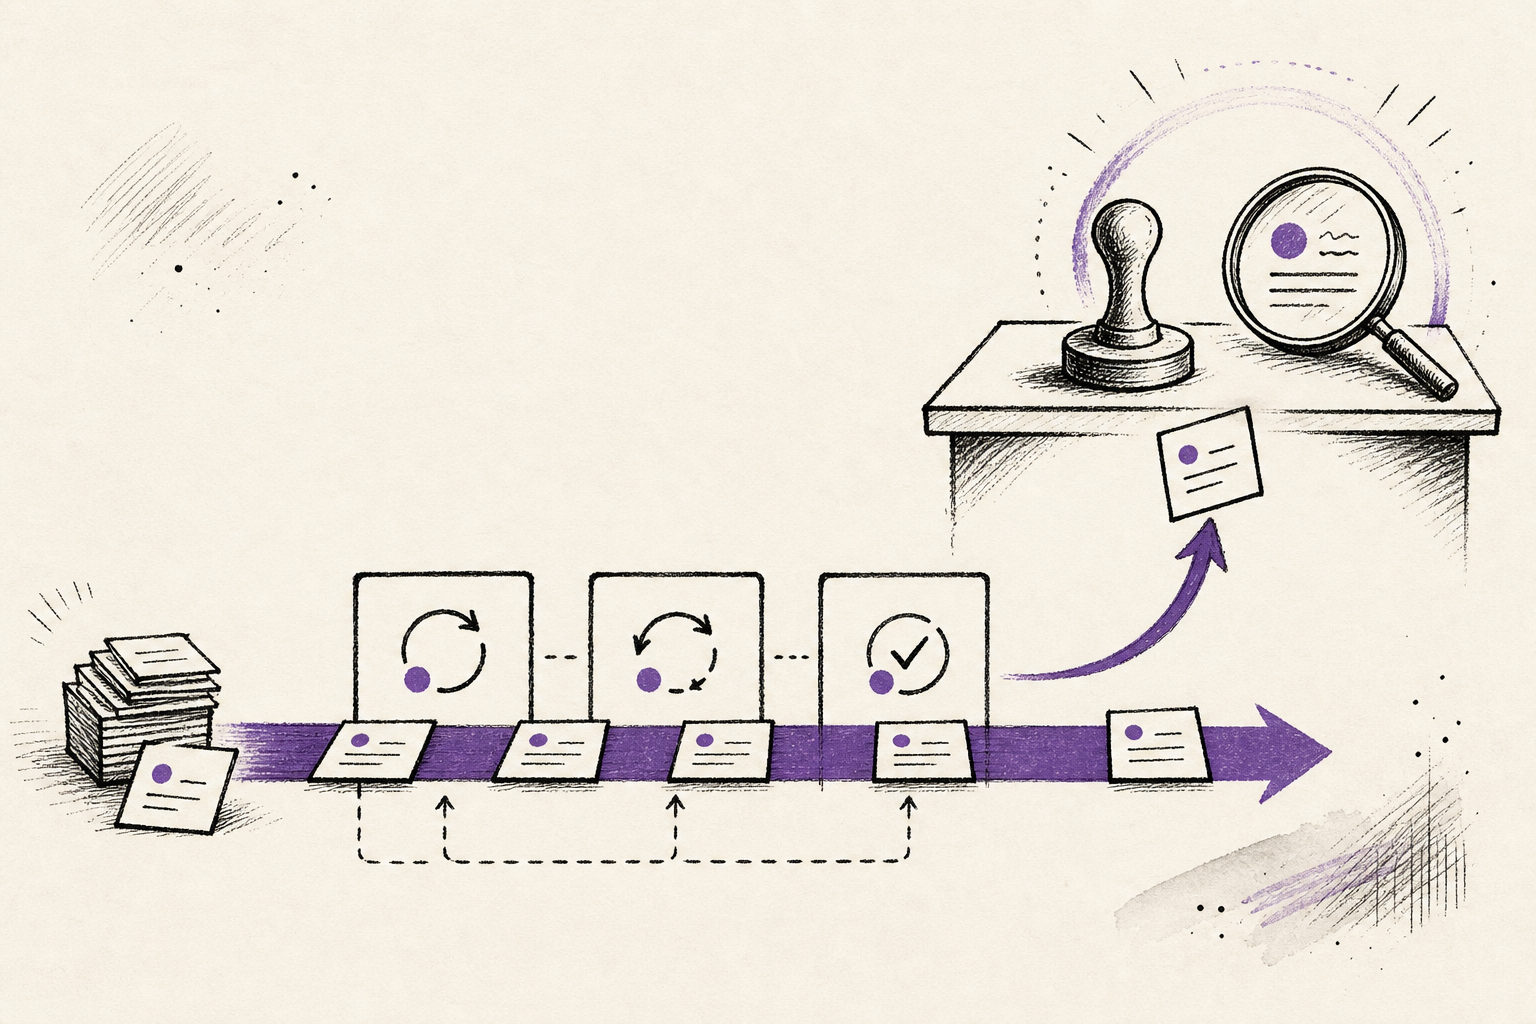
<p><a href="https://openai.com/index/gpt-5-6/">GPT-5.6 Sol</a> and <a href="https://www.anthropic.com/news/claude-fable-5-mythos-5">Claude Fable 5</a> still belong in the picture. They are ceiling models: the systems I would reach for when judgement, reliability, difficult reasoning, long-running work, and final review are worth more than raw speed.</p>

<p>The July 9 update makes the trade-off more concrete. <a href="https://artificialanalysis.ai/articles/gpt-5-6-has-landed">Artificial Analysis scores GPT-5.6 Sol</a> at 80 on its Coding Agent Index and 54 on its Agentic Index, while Fable 5 remains narrowly ahead on general intelligence. OpenAI has also announced a separate selected-customer Cerebras route for Sol at up to 750 tokens per second. That is not broad self-serve availability, but it shows frontier quality and high-speed serving starting to converge.</p>

<p>So I would not turn this into a universal "Cerebras fast, Claude/GPT slow" argument.</p>

<p>The better frame is routing.</p>

<p>Use the fast model for motion. Use the ceiling model for judgement. Keep the human close enough to decide when the work should move from one lane to the other.</p>

<figure class="kg-card kg-image-card kg-card-hascaption"><img src="https://storage.ghost.io/c/ea/80/ea80b01b-c9d0-45fd-a95f-5fbcd52ed925/content/images/2026/05/fast-inference-routing.png" class="kg-image" alt="Hand-drawn routing diagram showing small task cards moving through a fast lane before one card is escalated to a review desk with a stamp and magnifying glass." loading="lazy"><figcaption>The likely pattern is routing: fast model for motion, stronger model for judgement, human still deciding when to escalate.</figcaption></figure>

<p>That feels closer to how I actually use these tools.</p>

<p>Sometimes I want the cleverest model in the room. Sometimes I want a very fast model to do the next six small moves while I am still looking at the problem.</p>

<p>Those are different jobs.</p>

<h2 id="i-built-a-speed-lab-for-the-feeling">I built a speed lab for the feeling</h2>

<p>The annoying thing about token speed is that it sounds abstract until you feel it.</p>

<p>So I built <a href="https://www.bobzhu.tech/inference-speed-lab/">Inference Speed Lab</a> as the companion piece. It is a small timing model, not a benchmark. The fast lane defaults to 981 output tokens per second because that is the Cerebras Kimi K2.6 enterprise-trial measurement. The comparison lane is adjustable because GPT-5.6, Claude, and other frontier systems vary by model, mode, effort, provider, prompt, context, and workload.</p>

<p>At 981 output tokens per second, 500 output tokens take about half a second of generation time. At 55 output tokens per second, the same output takes about nine seconds.</p>

<p>Nine seconds is still survivable for one answer.</p>

<p>It is different across a loop.</p>
<div class="reader-artifact reader-artifact-linear" data-reader-artifact="linear">
  <div class="reader-linear-header">
    <span class="reader-linear-key">LOOP-981</span>
    <span class="reader-linear-status">Inside attention</span>
  </div>
  <h3 class="reader-artifact-title reader-linear-title">A fast supervised loop</h3>
  <p class="reader-linear-summary">One fast answer is the small version. The larger move is several bounded passes staying close enough for the human to steer.</p>
  <div class="reader-linear-meta">
    <span>Owner: human</span>
    <span>Model: fast executor</span>
    <span>Escalation: judgement model</span>
  </div>
  <div class="reader-linear-track">
    <div class="reader-linear-step is-done">
      <div>
        <p class="reader-linear-step-title">Draft the first version</p>
        <p class="reader-linear-step-note">Produce the rough answer while the human still has the intent in mind.</p>
      </div>
      <span class="reader-linear-estimate">fast</span>
    </div>
    <div class="reader-linear-step is-done">
      <div>
        <p class="reader-linear-step-title">Run the critic</p>
        <p class="reader-linear-step-note">Look for the risky assumption, missing source, or likely failure point.</p>
      </div>
      <span class="reader-linear-estimate">same turn</span>
    </div>
    <div class="reader-linear-step is-active">
      <div>
        <p class="reader-linear-step-title">Repair or escalate</p>
        <p class="reader-linear-step-note">Fix the ordinary weakness quickly, or route the hard judgement to a ceiling model.</p>
      </div>
      <span class="reader-linear-estimate">human call</span>
    </div>
  </div>
</div>
<p>Eight calls, each producing a few hundred tokens, can either feel like one interaction or like a background task. Add retrieval, tool calls, tests, and repair, and the difference becomes more than convenience. It changes whether the work remains supervised.</p>

<p>That is why the app belongs with the essay. It turns a benchmark-shaped claim into a small physical feeling: the fast lane keeps moving while the slower lane is still warming up.</p>

<h2 id="fast-errors-are-still-errors">Fast errors are still errors</h2>

<p>There is a boring caveat here, but it is the caveat that keeps the argument honest.</p>

<p>Fast wrong answers are still wrong.</p>

<p>A model can produce a bad patch quickly. It can skip the one test that would have caught the problem. It can write plausible research notes that quietly overstate the evidence. A faster model with a weak loop is not a better system. It is just a more energetic one.</p>

<p>The useful pattern is speed plus verification.</p>

<p>If another pass is cheap in wall-clock time, the product can afford to ask:</p>

<ul><li>did this answer actually satisfy the instruction?</li>
<li>what assumption would break it?</li>
<li>which file, source, or test supports the claim?</li>
<li>is this ordinary execution work or judgement work?</li>
<li>should this move to a stronger model?</li></ul>

<p>Those checks are where speed becomes useful. The model does more motion, but the system keeps asking whether the motion deserves to continue.</p>

<h2 id="the-future-also-gets-faster">The future also gets faster</h2>

<p>AI progress is usually described vertically.</p>

<p>Bigger model. Better benchmark. Higher ceiling.</p>

<p>That view is still useful, and I keep writing about it. But it misses the horizontal change: how much useful model work can happen inside a normal human moment.</p>

<p>That is why Cerebras feels interesting beyond the IPO. The company is pointing at a faster chip and a faster endpoint, but the part that feels more durable is the rhythm it creates for AI software.</p>

<p>The old rhythm was:</p>

<p>Ask. Wait. Review. Retry.</p>

<p>The new rhythm starts to look more like:</p>

<p>Draft. Check. Repair. Compare. Escalate. Return.</p>

<p>That second rhythm is closer to actual thinking with a tool. It is messy, iterative, and supervised. It does not remove the human. It gives the human more chances to steer before the thread breaks.</p>

<p>That is the version of the future that feels most concrete to me right now.</p>

<p>Not one magic answer.</p>

<p>More useful loops before you lose the thought.</p>

<h2 id="try-this-prompt">Try this prompt</h2>

<p>Pick one workflow I currently use AI for. Split it into the fast-motion parts and the judgement parts. For the fast-motion parts, design a loop that drafts, checks, repairs, and summarises before I lose attention. For the judgement parts, name when the work should escalate to a stronger model or back to me. End with the smallest version I could test this week.</p>

<h2 id="related-on-this-site">Related on this site</h2>

<ul><li><a href="https://www.bobzhu.tech/inference-speed-lab/">Inference Speed Lab</a> is the companion timing model for feeling the gap between near-1,000-token-per-second inference and slower repeated loops.</li>
<li><a href="https://www.bobzhu.tech/the-floor-and-ceiling-of-ai/">The Floor and Ceiling of AI</a> is the related frame for understanding open model capability against the proprietary frontier.</li>
<li><a href="https://www.bobzhu.tech/ai-is-moving-from-chatbots-to-operating-systems/">AI Is Moving From Chatbots to Operating Systems</a> explains why model quality now needs to be understood alongside tools, agents, and workflow architecture.</li></ul>

<h3 id="sources">Sources</h3>

<ul><li><a href="https://www.cerebras.ai/press-release/cerebras-systems-announces-filing-of-registration-statement-for-proposed-initial-ipo">Cerebras IPO filing announcement</a></li>
<li><a href="https://www.cerebras.ai/code">Cerebras Code GLM 4.7 page</a></li>
<li><a href="https://inference-docs.cerebras.ai/resources/glm-47-migration">Cerebras GLM 4.7 migration docs</a></li>
<li><a href="https://inference-docs.cerebras.ai/resources/designing-for-cerebras">Cerebras design guide for ultra-fast inference</a></li>
<li><a href="https://www.cerebras.ai/blog/cerebras-kimi-k2-Enterprise">Cerebras Kimi K2.6 enterprise-trial measurement</a></li>
<li><a href="https://huggingface.co/moonshotai/Kimi-K2.6">Kimi K2.6 model card</a></li>
<li><a href="https://openai.com/index/gpt-5-6/">OpenAI GPT-5.6 general availability</a></li>
<li><a href="https://artificialanalysis.ai/articles/gpt-5-6-has-landed">Artificial Analysis GPT-5.6 benchmarks</a></li>
<li><a href="https://www.anthropic.com/news/claude-fable-5-mythos-5">Anthropic Claude Fable 5 announcement</a></li></ul>